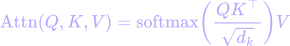01PAPERS · ARXIV
Two papers, one idea.
Paper I studies how to preserve attention outputs under value projection. Paper II examines which model properties predict sensitivity to compression.
FILE 01 · PAPER I · 2026arXiv:2604.11501
Attention-Weighted Value Projection for KV-Cache Compression
With attention weights fixed, Paper I derives the optimal orthogonal rank-r value projection and its reconstruction error. It extends that objective to calibration datasets and grouped-query attention, and examines where local error stops predicting downstream loss.
KV cacheSoftmax geometryExact solutionGrouped-query attentionv2 · corrected
FILE 02 · PAPER II · 2026arXiv:2604.20682
Variance Is Not Importance: Structural Analysis of Transformer Compressibility Across Model Scales
Over 40 experiments on GPT-2 and Mistral 7B identify five structural properties relevant to compression. High-variance directions are not necessarily the ones that matter for prediction, and transformer blocks grow more linear with depth: on Mistral 7B, R² rises from 0.17 at block 0 to 0.93 at block 31.
Spectral analysisVariance ≠ importanceOver 40 experiments