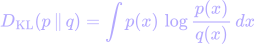

> FRAQTL TEST LAB · BENCHMARK LOG
> EVERY NUMBER WITH ITS BASELINE, SCOPE AND LIMITS

Every number, measured.Every limit, stated.

Two kinds of result, kept apart on purpose. Serving: Membrane, our inference engine, runs the KV cache compressed on NVIDIA GPUs. Models: our Hi-Fi builds target fidelity; Nano prioritizes smaller files with a larger quality tradeoff. Model cards document each comparison. Neither result implies the other.

MODEL FAMILIES WE COMPRESS Qwen Gemma Llama Mistral LFM2 FrogNano Open models from their makers, compressed by fraQtl. No affiliation implied.
Zero-based chartsBaseline named on every rowLimits next to the numberPublic model cards linked
01SERVING · KV CACHE · NVIDIA

More users on the same GPU.

Long conversations fill GPU memory with the KV cache, the model’s working memory. Membrane stores it compressed, so more users fit at full 128K context.

TEST A · CONCURRENT USERS AT 128KMEASURED 2026-10-31
17

users at 128K on one H100, where FP8 KV fits 9

1.31× faster per user than vLLM’s native 4-bit KV, using 3% more memory per token. Accuracy: no significant difference (mean KL, 30 documents); equivalence not shown.

QWEN3.8-27B · ONE H100 · 128K CONTEXT PER USER
KV cacheUsers that fitPer-user decodeAccuracy vs FP8 KV
fraQtl Membrane17≈12 tok/s at 17 usersSlightly below (mean KL 0.075 vs 0.066)
FP8 KV9≈19 tok/s at 9 usersReference
Qwen3.8-27B1 × H100128K per userstock vLLM + one pip install+3% memory per token vs vLLM 4-bit KV
LIMITS
  • Accuracy slightly below FP8 KV (mean KL 0.075 vs 0.066, 30 docs, p=0.009).
  • Per-user speed equals FP8 at 9 users each; at 17 users each user decodes slower (≈12 vs ≈19 tok/s).
  • This is a capacity result: more users at a lower per-user speed, not more users at the same speed.
TEST A2 · SECOND MODEL · GEMMA-4-E4BH100 · 128K
100

users held at 128K on one H100, vs FP8’s 46

Answer score not significantly different from FP8 on 300 real questions (169 vs 167 correct, p ≥ 0.69). Gemma-4-E4B, one H100, 128K context, our Q4 weights and KV together.

LIMITS
  • At 100 users each user decodes ≈8.7 tok/s vs FP8’s 19.6; 86 users stay above 10 tok/s each; part of the gain is our Q4 weights, not the KV cache alone.
EARLIER SERVING RECEIPTPUBLISHED AUG 17, 2026
Qwen3-4B-Instruct-25079 users × 128K on one A100 where FP8’s best is 4 and fp16 fits 2; 134.1 tok/s aggregate; 9/9 needles.A100
02MODELS · WEIGHTS · ON DEVICE

Same file size, closer to the original.

We compress the model weights so the small file behaves more like the full model. We measure closeness as KL divergence to the original’s outputs; lower is closer.

TEST B · QWEN3.5-4B · FILE C1PUBLIC ON HUGGING FACE
37.8%

closer to the original on task text

28.4% on general text, than the Q4_0 from the most-downloaded Qwen3.5-4B GGUF, at fewer bytes, same speed on the Snapdragon NPU with every tensor on the NPU. That repo’s Q4_K_S and IQ4_NL at the same size are closer on general text; see the model card.

FRAQTL C1 VS THE MOST-DOWNLOADED Q4_0 · QWEN3.5-4B
MeasurefraQtl C1Most-downloaded Q4_0Read as
Closeness to original, task text37.8% closerbaselineLower KL to bf16
Closeness to original, general text28.4% closerbaselineLower KL to bf16
GSM8K answers233233Same
IFEval answers194190Not significant
NPU prompt speed950 tok/s955 tok/sSame
NPU generation speed17.1 tok/s17.2 tok/sSame
Qwen3.5-4B4-bit Q4_0 formatKL to bf16 · 144 windowsSnapdragon NPU · every tensor on the NPU
LIMITS
  • Answers on 500 questions: GSM8K 233 vs 233, IFEval 194 vs 190 (difference not statistically significant). Closer to the original is not the same as more accurate.
  • Not faster than that Q4_0 on the NPU: speed is the same.
Qwen3.5-4B-fraQtl-Q4_0.gguf · sha256 dfae49c2f6fbc76aedcf121e22cc71b65d2c862ccdb79b9bc0f7cd1a9eedbffe
03RECEIPT LOG · SHIPPED MODELS

Published builds across six model families.

Earlier compact models, each public on Hugging Face with its numbers on the model card. Each row links to its model card and comparison details.

MODEL · CLOSER TO THE ORIGINAL · BASELINEON HUGGING FACE
Qwen3.5-4B Hi-Fi22.7% closer on task text · 17.3% on general textvs the most-downloaded Q4_K_M, in a slightly smaller file. Answer-score differences not significant (GSM8K 226 vs 227, IFEval 193 vs 194). Model card ↗NEW
FrogNano-4B20.3% closer on task text · 6.5% on general textvs the most-downloaded Q4_K_M at the same 4-bit size. Answer-score differences not significant (GSM8K 229 vs 229, IFEval 191 vs 190). Model card ↗NEW
Qwen3-4B-250755.9% closer on code/math · 46.4% on general textvs a community Q4_K_M at equal bytes; measured against a Q8_0 reference of the original. Model card ↗QWEN
Gemma-4-E4B16.2% closer on code/math · 4.2% on general textvs a community Q4_K_M at the same size. Model card ↗GEMMA
Gemma-4-E2B36% closer on code/math · 27% on general textvs a community Q4_K_M at the same size. Model card ↗GEMMA
LFM2-1.2B43% closer on task text · 23% on general textvs Liquid AI’s own Q4_K_M at the same size. Closeness only: not a claim of more accurate answers. Model card ↗LIQUID
37,085 downloads of our builds on Hugging Face, including mirrored copies; 9,058 in the last 30 days (Nov 13, 2026).
Closer = lower KL divergence to the original model’s outputs, from each public model card. Llama and Mistral repos are listed on our Hugging Face page.
04HOW WE MEASURE

How to read these numbers.

CLOSENESS (KL)

How far the compressed model’s next-token predictions drift from the original’s. Lower is closer. It measures fidelity, not answer accuracy, so we report answer tests separately.

ANSWERS

Right/wrong counts on public question sets, compared on the same questions. “Not significant” means the gap could be chance.

USERS THAT FIT

How many users at full 128K context the GPU holds at once. Always shown with per-user speed, because more users can mean slower decoding each.

BASELINES

Comparisons identify the cache format or model-file type; linked model cards provide artifact details. Different tests use different baselines; we don’t combine them.

Run it against your own workload.

Benchmarks show the method works. An evaluation shows what it does for your model, your context lengths and your hardware.