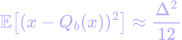> FRAQTL RESEARCH FACILITY · SECTOR Q
> MEMBRANE ENGINE · KV CACHE: COMPRESSED
> MEMBRANE · LONG-CONTEXT INFERENCE

Serve more long‑context usersper GPU.

fraQtl builds Membrane, a runtime that keeps AI’s working memory compressed while the model answers. It integrates with vLLM on NVIDIA GPUs to help inference teams fit more concurrent conversations into GPU memory.

Request a Membrane evaluation See the measured comparison
17 conversationsat 128K on one H100, versus 9 with FP8 KV · measured on Qwen3.8-27B ▸At those capacities: about 12 versus 19 tokens per second per user. See the quality and speed tradeoffs.
Benchmarked on NVIDIA H100 with vLLM. Contact us to discuss an evaluation.
◆ FACILITY BULLETIN
17 USERS AT 128K ON ONE H100, where FP8 KV fits 9 · Qwen3.8-27B▚▚ 37.8% CLOSER TO THE ORIGINAL on task text, 28.4% on general text, than the Q4_0 from the most-downloaded Qwen3.5-4B GGUF, at fewer bytes (its Q4_K_S and IQ4_NL are closer on general text) · Qwen3.5-4B▚▚ 37,085 DOWNLOADS OF OUR BUILDS, INCL. MIRRORED COPIES · NOV 13▚▚ NVIDIA GPU: BENCHMARKED▚▚ QUALCOMM NPU: PORT IN PROGRESS▚▚ AMD GPU: DESIGN DEFINED▚▚ CPU: LLAMA.CPP▚▚
// BUILT IN THE OPEN · CHECK EVERYTHING
vLLMMembraneCompressed working memory, integrated with vLLM. 17 vs 9Measured resultsModel, hardware, baseline and limits shown. HF ↗Downloadable modelsHi-Fi and Nano builds on Hugging Face. 2ResearchTwo public papers; product results measured separately.
HOW IT WORKSFROM YOUR MODEL TO SERVING
SECTOR 01TEST LAB · RESULTS

Two ways to reduce AI memory.

Membrane reduces the working memory used while serving requests. Our model builds compress the model itself. Each has its own comparison.

MEMBRANE · SERVING CAPACITY2026-10-31
0

users at 128K on one H100, where FP8 KV fits 9

1.31× faster per user than vLLM’s native 4-bit KV, using 3% more memory per token. Accuracy: no significant difference (mean KL, 30 documents); equivalence not shown.

fraQtl Membrane17 users
FP8 KV cache9 users
0918 users
Qwen3.8-27B · one H100 · 128K context per user · stock vLLM + one pip install

LIMITS· Accuracy slightly below FP8 KV (mean KL 0.075 vs 0.066, 30 docs, p=0.009).· Per-user speed equals FP8 at 9 users each; at 17 users each user decodes slower (≈12 vs ≈19 tok/s).Measured October 31, 2026.

REQUEST THE SERVING REPORT ▸
HI-FI MODELS · MODEL FIDELITYFILE C1
0.0%

closer to the original on task text

28.4% on general text, than the Q4_0 from the most-downloaded Qwen3.5-4B GGUF, at fewer bytes, same speed on the Snapdragon NPU with every tensor on the NPU. That repo’s Q4_K_S and IQ4_NL at the same size are closer on general text; see the model card.

Task text37.8% closer
General text28.4% closer
0%25%50%
Qwen3.5-4B · KL to bf16 · 144 windows · Snapdragon NPU

Answers on 500 questions: GSM8K 233 vs 233, IFEval 194 vs 190 (difference not statistically significant).

GET THE MODEL ON HUGGING FACE ↗ REQUEST THE MODEL REPORT ▸
MEMBRANE · SERVING CAPACITY · QWEN3.8-27B · 128K CONTEXT

One H100, filling up with long conversations.

ILLUSTRATION · PROPORTIONS FROM THE MEASURED 17 VS 9
ONE H100 · FP8 KV CACHE0 users
ONE H100 · fraQtl MEMBRANE0 users
0 users arriving
model weightsFP8 KV per userMembrane KV per userdoes not fit

Measured: 17 users at 128K on one H100, where FP8 KV fits 9 (Qwen3.8-27B, stock vLLM + one pip install). Speed and accuracy tradeoffs are stated in the serving result above. Grid proportions are chosen to match the measured capacities; it is not a memory map.

MODEL COVERAGE · PUBLIC ON HUGGING FACE

Published builds across six model families.

Every point is a public model you can download. Re-cluster them by family, format or size; hover to read one, click to open its model card. Logos belong to each model’s maker; no affiliation implied.

CLUSTER BY k = 6 · iteration 0
Hi-Fi weightsNPU weightsNano 2-bitKV sidecarPoint size = parameter count, log scale
    SECTOR 02THEORY DIVISION

    Every bit you remove leaves an error. We decide where it lands.

    Fewer bits means fewer levels to represent a signal. Our work is choosing what a model must keep, then measuring the difference against the original model and your workload.

    ILLUSTRATION · SCOPE: 4-BITLEVELS: 16 · RMS ERR: 0.000
    Original signal Quantized Error
    CONTAINMENT TEST · ILLUSTRATIONW + Σᵢ KVᵢ ≤ B
    SESSIONS
    HARDWARE MEMORY BUDGET WORKING MEMORY / KV CACHE ↑ MODEL WEIGHTS
    Weights and working memory share one fixed budget.
    SECTOR 03MEMORY CONTAINMENT

    The model is only part of the memory bill.

    Model weights store what a model has learned. As it generates an answer, its working memory—the KV cache—stores information about the context it has already read. Longer conversations and more concurrent users make that cache grow.

    fraQtl works on both: compact model weights and efficient execution over a compressed KV cache.

    SECTOR 04MODEL FOUNDRY

    Choose a model that fits your memory budget.

    Download a supported build and use its model card to compare file size, quality and runtime requirements.

    Hi-Fi: fidelity first. Compact builds with measured comparisons to the original model and named quantized baselines.
    Nano: size first. Smaller files with a larger quality tradeoff. Check the model card before choosing this tier.
    BROWSE RELEASED MODELS ↗
    RECEIPT LOG · SHIPPED MODELSON HUGGING FACE
    Qwen3.5-4B Hi-Fi NEW22.7% closer on task text · 17.3% on general textvs the most-downloaded Q4_K_M, in a slightly smaller file. Answer-score differences not significant (GSM8K 226 vs 227, IFEval 193 vs 194).
    FrogNano-4B NEW20.3% closer on task text · 6.5% on general textvs the most-downloaded Q4_K_M at the same 4-bit size. Answer-score differences not significant (GSM8K 229 vs 229, IFEval 191 vs 190).
    Qwen3-4B-250755.9% closer on code/math · 46.4% on general textvs a community Q4_K_M at equal bytes; measured against a Q8_0 reference of the original.
    Gemma-4-E4B16.2% closer on code/math · 4.2% on general textvs a community Q4_K_M at the same size.
    Gemma-4-E2B36% closer on code/math · 27% on general textvs a community Q4_K_M at the same size.
    LFM2-1.2B43% closer on task text · 23% on general textvs Liquid AI’s own Q4_K_M at the same size.
    37,085 downloads of our builds on Hugging Face, including mirrored copies; 9,058 in the last 30 days (Nov 13, 2026).
    Closer = lower KL divergence to the original model’s outputs, from each public model card.
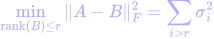
    SECTOR 05ENGINE ROOM

    Add compressed working memory to your serving stack.

    Membrane stores and uses a compressed KV cache inside vLLM. Our measured NVIDIA implementation targets long conversations where cache memory limits how many users fit on a GPU. We compare it with your current configuration on an agreed model and workload, measuring quality, memory and latency.

    Where it’s going: we are developing .fraqtl packages to carry model-specific execution settings and verification data across supported runtimes. Today Membrane runs on NVIDIA.

    EARLIER RECEIPT · AUG 2026
    9 users × 128K on one A100 where FP8’s best is 4 and fp16 fits 2; 134.1 tok/s aggregate; 9/9 needles. Qwen3-4B-Instruct-2507.

    Evaluate Membrane
    SECTOR 06INTAKE

    Start with your deployment.

    > FOR INFERENCE TEAMS

    For teams serving long conversations.

    Tell us your model, GPU, context lengths and latency target. We will agree on one comparison against your existing setup.

    Request an evaluation
    > FOR DEVELOPERS

    For developers running open models.

    Start with a published Hi-Fi or Nano build. Its model card lists the file, runtime, measurements and limitations.

    Choose a model ↗
    SECTOR 07SYSTEMS STATUS

    What runs today. What comes next.

    Portable delivery is the next step.

    We are developing .fraqtl packages to carry model-specific execution settings and verification data across supported runtimes. Sidecar delivery next to standard model files is the current direction.

    PLATFORM STATUS
    NVIDIA GPU
    Membrane built, integrated into vLLM, and benchmarked.
    [BENCHMARKED]
    Qualcomm NPU
    Membrane port in progress.
    [IN PROGRESS]
    AMD GPU
    Membrane design defined; implementation pending.
    [DESIGN DEFINED]
    CPU
    Current execution uses llama.cpp.
    [LLAMA.CPP]
    SECTOR 08TEST PROTOCOL

    Agree on the test before the work starts.

    1. 01

      Define the workload

      Select the model, hardware, and user task.

    2. 02

      Set the criteria

      Agree on the baseline and the quality, memory, and latency requirements.

    3. 03

      Measure the result

      Review the comparison and decide whether to proceed with deployment.

    SECTOR 09ARCHIVE · RESEARCH

    The research behind it.

    ALL RESEARCH ▸
    FILE 01 · PAPER I · arXiv:2604.11501 Attention-Weighted Value Projection for KV-Cache Compression With attention weights fixed, the optimal rank-r value projection and its reconstruction error, extended to calibration data and grouped-query attention. READ ON arXiv ↗ FILE 02 · PAPER II · arXiv:2604.20682 Variance Is Not Importance: Structural Analysis of Transformer Compressibility Across Model Scales High-variance directions are not necessarily the ones that matter downstream. Over 40 experiments on GPT-2 and Mistral 7B. READ ON arXiv ↗
    SECTOR 10FIELD NOTES

    Longer-form thinking on inference economics.

    ALL NOTES ▸
    NOTE 01 · ESSAY · JUL 27, 2026 The AI Race Has a Second Front After building more capable AI, the next race is spending only the compute each task needs, measured as cost per successful task. READ THE ESSAY ▸ PRESS · PRIMARY · SEP 18, 2026 Language models compress their memory by tracking how attention mixes tokens Independent coverage of Paper I and the attention-weighted value projection, alongside Eigen Attention, WeightedKV, ReCalKV and STAR-KV. READ THE ARTICLE ↗

    Test Membraneon one workload.

    Bring your current setup. Agree on the quality and latency requirements, then measure whether Membrane improves useful capacity.

    Request a Membrane evaluation contact@fraqtl.ai